SEO is one of the major considerations for any AEM website. To make sure crawlers find and crawl the site correctly, it needs a sitemap.xml and a robots.txt that points crawlers to that sitemap.
A robots.txt file lives at the root of the website. It acts as the entry point for crawlers and makes sure they access only the parts of the site we have allowed.
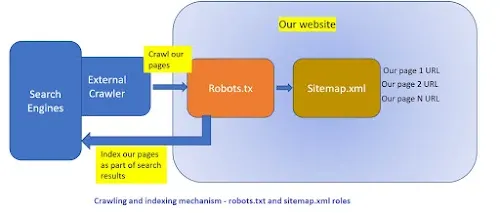
Implementing robots.txt in an AEM website
There are several ways to do this; the one below is among the simplest. Say we have a multilingual site with the language roots /en, /fr, /gb and /in.
1. Add robots.txt in the author instance
Log in to CRXDE and create a file called robots.txt under /content/dam/[sitename]. Add the following lines to it on the author instance, then publish it.
# Any search crawler can crawl our site
User-agent: *

# Allow only the paths below
Allow: /en/
Allow: /fr/
Allow: /gb/
Allow: /in/
# Disallow everything else
Disallow: /

# Crawl all the sitemaps below
Sitemap: https://[sitename]/en/sitemap.xml
Sitemap: https://[sitename]/fr/sitemap.xml
Sitemap: https://[sitename]/gb/sitemap.xml
Sitemap: https://[sitename]/in/sitemap.xml
2. Add an OSGi configuration for URL mapping
In the OSGi console (/system/console/configMgr), open Apache Sling Resource Resolver Factory and add this entry under URL Mappings:
/content/dam/sitename/robots.txt>/robots.txt$3. Allow robots.txt through the dispatcher
Add an allow rule to the dispatcher so crawlers can reach the file:
/0010 { /type "allow" /url "/robots.txt" }Now www.[sitename]/robots.txt returns the file on the public domain. Any search engine that visits the site reads it to learn whether it may crawl the site and which areas it may crawl.
Sample robots.txt rules
# Disallow googlebot from example.com/directory1/... and example.com/directory2/...
# but allow access to directory2/subdirectory1/...
# All other directories on the site are allowed by default.
User-agent: googlebot
Disallow: /directory1/
Disallow: /directory2/
Allow: /directory2/subdirectory1/

# Block the entire site from xyzcrawler.
User-agent: xyzcrawler
Disallow: /
If the site should also hide the /content prefix from its public URLs, see hiding the /content root path in publish and website domains.